A regional lending platform automated its credit risk scoring model and, after strong test results, reduced manual review on mid-tier applications. Six months later, an audit found a cluster of approvals far above historical norms, several already defaulted. The cause: a third-party data vendor had quietly shifted “high risk” labels to “low risk” over several months. The model had learned exactly what it was taught.
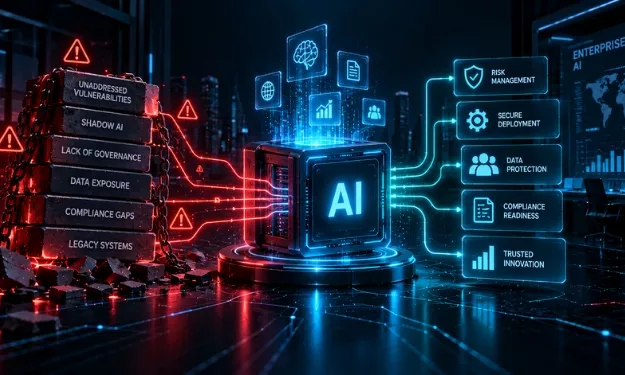
This is the practical face of AI data poisoning: not a breach alert, but a model doing its job confidently on a corrupted foundation. For CISOs and governance leaders, understanding how this attack works across training pipelines and RAG architectures is now a baseline requirement.
What Is AI Data Poisoning?
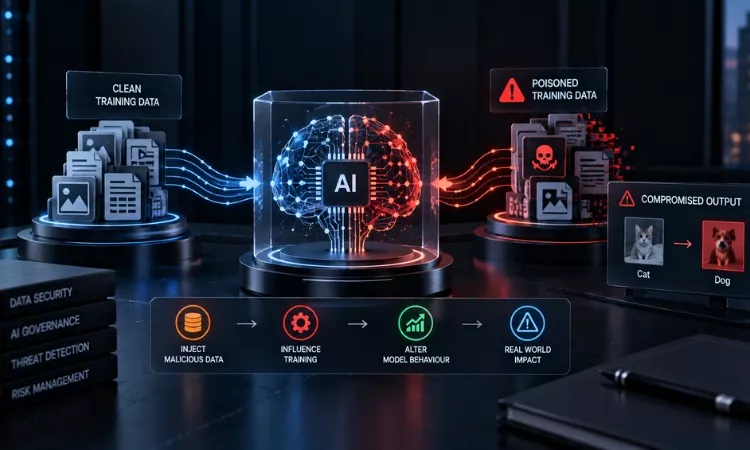
AI data poisoning is an adversarial attack where a threat actor tampers with the data used to train, fine-tune, or ground an AI system so its behavior changes in the attacker’s favor: injecting false records, mislabeling samples, or corrupting external knowledge bases. Because the manipulation happens before deployment or during continuous learning, the flaw stays latent until a specific input triggers it.
In the MITRE ATLAS taxonomy, this is formalized under:
- AML.T0020 (Poison Training Data): Adversaries modify training datasets to manipulate model behavior.
- AML.T0018.000 (Poison AI Model): Embedding a latent trigger during training. (Formerly “Backdoor ML Model” before ATLAS’s 2026 naming refresh; the ID is unchanged.)
- AML.T0010 (AI Supply Chain Compromise): Tampering with open-source models, data, or pipeline dependencies before ingestion.
Why Is It a Critical Enterprise Risk?
Automated credit underwriting, fraud scoring, code generation, and resume filtering all depend on training data pulled from public repositories, commercial aggregators, or web scrapers. Three shifts have widened the risk: continuous fine-tuning on streaming data removes the old “train once” security posture; most models build on open-source bases from hubs like Hugging Face, exposing them to typosquatting and compromised pull requests; and regulation now treats data governance as enforceable. CAISS program trains teams to simulate this exact attack class before an adversary does.
Under Article 10 of the EU AI Act (Regulation (EU) 2024/1689), high-risk AI systems must implement rigorous data governance and bias examination. Under Article 99, non-compliance carries fines up to €15 million or 3% of worldwide turnover; violations of prohibited practices (Article 5) reach €35 million or 7%.
How Do Attackers Corrupt Training Data?
Poisoning requires remarkably little data to succeed. Shafahi et al. (NeurIPS 2018) showed a single crafted poison image achieved a 100% success rate in transfer learning, while roughly 1% of a training class achieved 60–70% success in full end-to-end training. Carlini et al. (IEEE S&P 2024) showed an adversary spending just $60 could poison 0.01% of web-scale datasets like LAION-400M or COYO-700M via split-view poisoning.
Dirty-label poisoning flips labels outright (easier to catch with consensus checks). Clean-label poisoning keeps labels accurate but perturbs the feature space so the model binds the correct label to a hidden pattern, evading manual review entirely.
Common entry points: unverified web scraping (via expired-domain takeovers), compromised crowdsourced labeling, and third-party data feeds, the exact failure mode in the lending scenario above, which sits squarely in third-party risk territory. See Ampcus Cyber’s TPRM services.
RAG and Generative AI Are Not Immune
Organizations using off-the-shelf LLMs often assume they’re safe since they don’t train base weights. But RAG pipelines introduce a poisoning surface at the retrieval layer: internal documents (SharePoint, Confluence, tickets) get embedded into a vector database, and poisoned entries can hijack retrieval for high-value queries or smuggle in hidden instructions that override system prompts during inference. Because the base LLM is untouched, weight validation won’t catch it, defense has to secure the knowledge corpus and ingestion pipeline itself. This is formalized under OWASP’s LLM Top 10 (2025) as LLM04 (Data and Model Poisoning) and LLM08 (Vector and Embedding Weaknesses).
Data poisoning vs. prompt injection: poisoning corrupts weights or embeddings and persists until the pipeline is purged and retrained; prompt injection is an ephemeral runtime attack fixed with guardrails and input sanitization, though logs must still be quarantined so they don’t poison future retraining data.
Detecting and Preventing It
Detection: maintain cryptographic data provenance (C2PA, Sigstore); use spectral signatures (SVD on activation layers) to isolate poisoned clusters; run sanitization algorithms like RONI or TRIM before committing weight updates; and red-team specific data slices, since global accuracy metrics hide targeted backdoors. Ampcus Cyber’s Red Team Assessment applies this discipline to production ML systems.
Prevention: apply DP-SGD gradient clipping (not a standalone defense, but effective paired with filtering); version-control datasets like code with RBAC; audit third-party data vendors continuously rather than at intake, Wizard is built for this; harden the RAG ingestion boundary against hidden markdown injection; and keep verified checkpoint rollbacks ready.
Governing Frameworks
- NIST AI RMF 1.0: operationalizes data security under MAP, MEASURE, and MANAGE functions.
- MITRE ATLAS: maps AML.T0020, AML.T0018.000, and AML.T0010 to concrete countermeasures.
- ISO/IEC 42001:2023: Annex A.7 covers data acquisition, quality, and provenance for AI systems.
- OWASP LLM Top 10 (2025): LLM04 and LLM08.
Coordinating these instead of tracking each in isolation is what GRACE platform and vCISO advisory are built for.
Protect your AI systems from the ground up.
| Talk to Ampcus Cyber about securing your training pipelines, auditing RAG architectures, and building an AI governance program before an attacker exploits the gap. |
People Also Ask
Can poisoning be fixed without full retraining?
Rarely cleanly. Machine unlearning is emerging, but the current standard is to quarantine, purge the poisoned data, and roll back to a verified clean checkpoint.
Can RAG be poisoned without touching model weights?
Yes. Injecting manipulated documents into knowledge stores corrupts retrieval, achieving the same effect without altering a single weight.
Is DP-SGD a complete defense?
No. It bounds any single record’s influence but doesn’t stop coordinated multi-sample or clean-label attacks; pair it with filtering and provenance checks.
What are the EU AI Act penalties?
Up to €15 million or 3% of turnover for high-risk data governance failures (Article 10); up to €35 million or 7% for prohibited practices (Article 5).
Who owns preventing this?
Data engineering and MLOps own the technical pipeline; security and GRC leaders, the CISO or vCISO, own the governance architecture and vendor standards.
Enjoyed reading this blog? Stay updated with our latest exclusive content by following us on Twitter and LinkedIn.